The Pilot Project Myth: A Trial Is Not a Verdict
A policy pilot can show what works in one setting. Learn how to read its limits before treating a promising local result as proof for wider use.
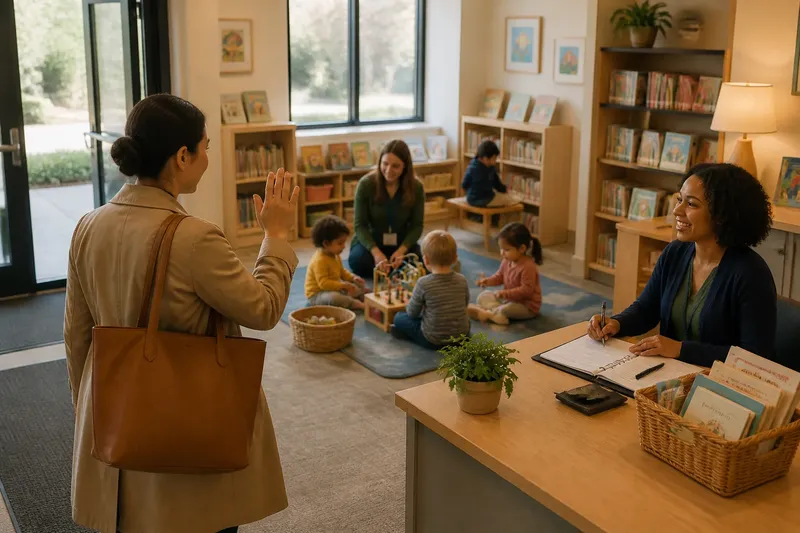
At a neighborhood library, a parent drops off a toddler and hurries to a job interview. The library is hosting a small pilot that offers supervised child care during weekday mornings. A few months later, families and staff say the service has helped. That is useful evidence, but it does not settle whether the policy will work across the city. A policy pilot can reveal how an idea behaves in one setting; it cannot, by itself, deliver a verdict for every setting.
The distinction matters because pilots are often designed to answer a narrow question: can a proposed service be organized and used here? A favorable answer may support further evaluation. It does not establish that the service will reach the same people, run under the same conditions, or produce the same results elsewhere.
What the pilot showed
Imagine the city’s invented pilot has a simple purpose: offer short-term child care while parents use library services or attend nearby appointments. The city selects one branch with a large children’s room, an accessible entrance, and staff who already know many local families. The pilot runs during weekday mornings, when a partner nonprofit can provide trained caregivers.
At the end, the city has several meaningful observations. Parents used the service. Caregivers could manage drop-offs in that room. Staff found a workable way to coordinate bookings. Some families said the care made it easier to attend an appointment or use the library. These findings can help decision-makers judge whether the basic service is feasible and what may need adjustment.
But the observations are local. They describe a particular branch, schedule, staffing arrangement, partner, and group of families. The result is not a general rule. In evaluation, feasibility means that an approach can be delivered under specified conditions. Effectiveness asks whether it produces the intended benefit, and for whom. Transferability asks whether the result is likely to hold in a different setting. Those questions overlap, but none answers the others automatically.
Policy pilot limits
A promising pilot can look stronger than it is when its context stays in the background. The selected library may be unusually easy to reach. Its room may already suit child care. A nonprofit may contribute expertise that other branches do not have. If the city expands the service without recording these conditions, decision-makers may mistake the advantages of the location for qualities of the policy itself.
Participation also shapes what the pilot can tell the city. Families who already visit that branch may be more likely to hear about the service and try it. Parents who work evenings, need care for older children, speak a language not supported by the booking process, or do not feel comfortable leaving a child with an unfamiliar provider may be absent from the feedback. Their absence does not show that they have no need. It means the pilot has limited evidence about their circumstances.
Duration and timing matter, too. A short trial may capture the novelty of a new service, an unusually calm period, or a temporary staffing arrangement. It may not reveal what happens when demand changes, a partner’s availability shifts, or staff must balance the service with their regular duties. A pilot can be well run and still leave these questions open.
Questions behind results?
What did the pilot actually measure?
Separate activity from outcome. A record of bookings shows that people used the service; it does not, on its own, show that they reached appointments or experienced less difficulty finding care. Identify which outcomes were observed and which remain assumptions.
Who took part, and who did not?
Look at how participants heard about the pilot, who could use its hours and location, and whose feedback was gathered. These details help show which communities the results describe and where the evidence is thin.
What conditions made delivery possible?
Check for resources that may not be available everywhere, such as a suitable room, an established community partner, or staff with relevant training. A policy that depends on those supports may need a different design or added capacity in another location.
What changed during the trial?
Ask whether eligibility, opening hours, staffing, or the booking process shifted while the pilot was running. Changes can be sensible, but they affect what was evaluated and should be visible in the account of the results.
From local result to decision
Suppose the city’s invented review finds that families used the library service and staff handled bookings reliably, but it has little information about families who did not already visit the branch. The sensible next decision is neither automatic citywide expansion nor dismissal of the idea. The city can record the service’s promising operational results, name what remains unknown, and choose a next evaluation that addresses those gaps.
For instance, officials might invite a branch with different hours and a less suitable room to explore what adaptations would be needed. They could ask a community organization to help reach families who were not represented in the first round. They could also track whether participants were able to attend the appointments they identified, rather than relying only on booking counts. These are possible evaluation choices, not proof that expansion will succeed.
Before making a broader commitment, decision-makers can compare the pilot’s conditions with those of the proposed locations. They can identify which features appear essential, which might be adapted, and what resources delivery would require. If the policy’s purpose or audience changes during expansion, the evaluation should state that as well. Otherwise, a new version of the policy may be treated as though it were the same intervention the pilot examined.
Public communication should preserve these distinctions. “The service was feasible at one branch and participants described useful benefits” is more informative than “the pilot proved the model works.” The first statement gives readers a result and its boundary. It also leaves room to explain the next decision, including why the city is testing adaptations or collecting further evidence.
A verdict with boundaries
In the library scenario, the pilot’s value is not that it settles the future. It shows that a particular arrangement can operate in a particular place, and it gives the city practical questions to carry forward. If the city expands, adapts, pauses, or declines the service, each choice should be tied to what the evidence does and does not support.
When reading any policy pilot, treat the setting as part of the result, not background scenery. A clear account names who participated, what was delivered, what changed, and what outcomes were actually observed. That boundary is not a weakness to hide; it is the information a public decision needs before a local trial becomes a wider commitment.